How GPUs Multiply Matrices (CUDA Code Visualized)
3-Second Blueprint (English)
- Multiplying two 1,000-by-1,000 matrices requires one billion operations, bottlenecking CPUs that have only dozens of complex cores.
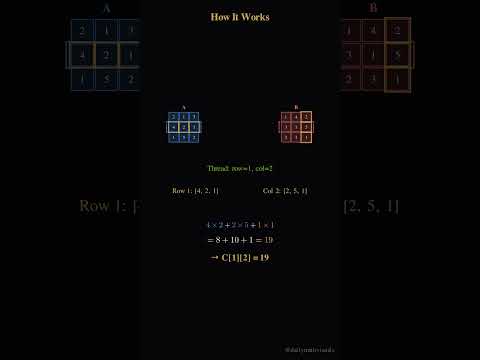
- In a CUDA kernel, each GPU thread maps to a specific row and column to compute one output cell's dot product independently.
- Launching thousands of parallel threads simultaneously executes identical math across massive tensor layers to power AI training.
CUDA KernelsMatrix MultiplicationGPU ParallelismDot Product
3-Sekunden-Fazit (Deutsch)
- Die Multiplikation zweier 1000×1000-Matrizen erfordert eine Milliarde Operationen und bremst CPUs mit wenigen komplexen Kernen aus.
- In einem CUDA-Kernel übernimmt jeder GPU-Thread eine feste Zeile und Spalte, um das Skalarprodukt einer Ergebniszelle zu berechnen.
- Tausende parallele Threads führen dieselbe Rechenoperation gleichzeitig auf verschiedenen Daten aus und ermöglichen KI-Training.
CUDA-KernelMatrizenmultiplikationGPU-ParallelitätSkalarprodukt
Note / Hinweis: Blueprints are AI-generated educational summaries (0% Politics · 0% Religion · 0% Brainrot) and do not constitute medical, legal, or financial advice. / KI-generierte Zusammenfassung zu Bildungszwecken – ersetzt keine medizinische, rechtliche oder finanzielle Fachberatung.