Tensor Cores in a Nutshell
3-Second Blueprint (English)
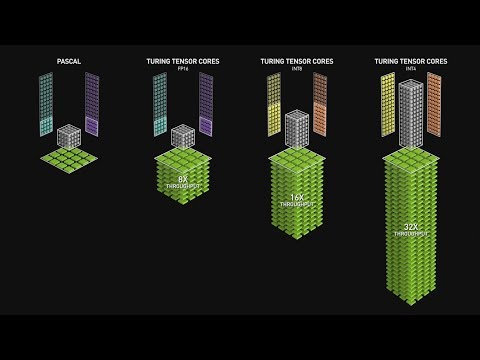
- NVIDIA Tensor Cores execute mixed-precision Matrix Multiply-Accumulate operations, multiplying FP16 inputs and accumulating in FP32.
- Accumulating in FP32 preserves model convergence while delivering around 4x end-to-end speedups on deep learning workloads.
- Developers invoke Tensor Cores automatically via cuDNN and cuBLAS or program fused ops with CUDA WMMA APIs and verify usage via nvprof.
Mixed-Precision FP16/FP32Matrix Multiply-AccumulateCUDA WMMA APInvprof Profiling
3-Sekunden-Fazit (Deutsch)
- NVIDIA-Tensor-Kerne führen Mixed-Precision-Matrixmultiplikationen aus, indem sie FP16-Eingaben multiplizieren und in FP32 akkumulieren.
- Die FP32-Akkumulation sichert die Netzwerkkonvergenz und erzielt in der Praxis rund vierfache End-to-End-Beschleunigungen beim Training.
- Entwickler nutzen Tensor-Kerne über cuDNN und cuBLAS, programmieren eigene Fused-Ops per CUDA WMMA und prüfen Kernel-Aufrufe mit nvprof.
Mixed Precision FP16/FP32Matrix-Multiply-AccumulateCUDA WMMA APInvprof-Profiling
Note / Hinweis: Blueprints are AI-generated educational summaries (0% Politics · 0% Religion · 0% Brainrot) and do not constitute medical, legal, or financial advice. / KI-generierte Zusammenfassung zu Bildungszwecken – ersetzt keine medizinische, rechtliche oder finanzielle Fachberatung.